For US product and engineering leaders
Hire AI developers for US teams: specialists who ship LLM features that hold up in production, with grounded answers, the right model for each request and evals before every release.
- Senior engineering oversight
- US workday overlap
- Your stack and controls
Start with one AI developer. Add a team when the product needs more capacity.
AI capacity, inside your org.
Generative AI engineers who work in your codebase, quality gates and release rhythm.
Built for product and engineering leadersOne senior AI developer to a full product team
- 01Years engineering software
- 20+
- 02Engineers under one roof
- 200+
- 03Clients served
- 300+
- 04Global delivery locations
- 4+
Dallas headquarteredDelivery across the USA, India, Canada and Mexico
Tools hired AI developers use
We work with the generative AI tools, frameworks and architecture your teams already use: LangChain, LangGraph, vector search and Python.
Core
- LangChainLLM framework
- LangGraphAgent workflows
- Hugging FaceOpen models
- QdrantVector search
- PGpgvectorVectors in Postgres
- PythonLanguage
Ecosystem
- Anthropic
- OpenAI
- Google Gemini
- Mistral AI
- Llama
- Ollama
- vLLM
- FastAPI
- Redis
We choose tools for your product, your data, your security needs and your deployment plan.
AI work we cover
The generative AI work our engineers take on, from RAG and agents through evals and model routing, and the tools they use every day.
Grounded answers
Retrieval over your own documents and data, with every answer citing its sources so people can check it.
Common work
- RAG pipelines
- Document ingestion
- Search tuning
Tools
- LangChain
- Qdrant
- pgvector
- Python
Agents that finish the job
Assistants that use your tools and APIs step by step, with clear limits and a person in the loop where it matters.
Common work
- Agent workflows
- Tool integration
- Human review
Tools
- LangGraph
- LangChain
- FastAPI
- Python
Evals before every release
Test suites for accuracy, groundedness and safety that run on every prompt or model change, so each release is measured.
Common work
- Eval suites
- Guardrails
- Regression testing
Tools
- Python
- LangChain
- Hugging Face
- GitHub Actions
The right model for the job
Requests routed to the model that fits them, hosted or open, so you don’t pay flagship prices for simple work.
Common work
- Model routing
- Cost control
- Fine-tuning
Tools
- Hugging Face
- Ollama
- vLLM
- Anthropic
Why JumpGrowth
Senior India-based engineers for US teams, backed by delivery across the USA, India, Canada and Mexico.
- Years engineering software
- 20+
- Engineers under one roof
- 200+
- Clients served
- 300+
Engineers matched to your work
Start from the AI stack, domain, seniority and delivery habits you actually need. Review profiles and test the technical fit before you choose.
- Specialists
- Domain experience
- Direct interviews
Your team keeps ownership
Your leads set priorities, review the work and own the roadmap. Our engineers join your rituals, your repositories and your release process.
- Your tools
- Your rituals
- Your roadmap
Capacity without the handoff
Nothing is thrown over a wall. Engineers work in your sprints with US workday overlap, so RAG, agents and evals move every day.
- US overlap
- Daily stand-ups
- Shared sprints
AI developer hiring models
Embed an AI developer in your team, add a small generative AI squad, or pair AI engineers with a dedicated delivery pod.
 Staff augmentation
Embed one AI developer
A dedicated AI specialist in your team, your codebase and your sprint cycle, reporting to your lead.
- LangChain
- LangGraph
- Hugging Face
 Augmented squad
Add a team of AI developers
Several AI developers for a clear gap across RAG, agents and evals, led by your own managers.
- LangGraph
- Hugging Face
- Qdrant
 Managed delivery pod
Pair AI with a pod
AI developers with a dedicated delivery pod, so features, data and release stay in one team.
- LangChain
- Architecture
- Delivery
You stay in control. Our engineers work in your codebase, your tools and your delivery process.
Cost savings calculator
Move the slider to compare a senior US generative AI team with an India-based team of the same size. Price depends on seniority, US overlap and whether you hire one developer or a pod.
A planning estimate: $90 an hour onshore and $32 offshore, 160 hours per person each month. Not a JumpGrowth quote. Final cost follows seniority, overlap and scope.
US onshore at $90/hr
$43,200
per month
Offshore at $32/hr
$15,360
per month
Estimated monthly savings
$27,840
About 64% lower than the US onshore estimate.
Get a costed plan for the AI roles, seniority and team shape you need.
Find the right skill
Pick a skill to see the kinds of engineers we match to your team: AI architect, LLM engineer, evaluation engineer or LLMOps engineer.
Senior specialty role
AI Solutions Architect
Sets the shape of your AI features: retrieval, models, data boundaries and the standards the team builds to.
- LangChain
- LangGraph
- Qdrant
- Python
Senior specialty role
LLM Engineer
Builds AI features end to end in your product, from the prompt and retrieval to the API and the interface.
- LangChain
- Python
- FastAPI
- pgvector
Senior specialty role
AI Evaluation Engineer
Builds the evals and guardrails that show whether a change made answers better or worse before it ships.
- Python
- Eval suites
- Guardrails
- LangChain
Senior specialty role
LLMOps Engineer
Runs models and pipelines in production, with hosting, routing, cost and latency watched every day.
- vLLM
- Ollama
- Docker
- Kubernetes
Example roles. We confirm availability and fit before you decide.
What our engineers do
Add the skills you need across RAG, agents, evals and model routing.
Build
Build AI features
Generative AI engineers who build assistants, copilots and agents that hold up in production.
- RAG
- Agents
- Copilots
Integrate
Connect your data
Specialists who connect models to your documents, databases, APIs and access controls.
- Vector search
- Tool calling
- LangChain
Platform
Run it securely
Engineers who host, route and monitor models inside your cloud and under your security rules.
- Model hosting
- Evals
- Security
How they help
Hire one AI developer or a generative AI team. We cover assistants, retrieval, evals and production.
- 01
Build AI into your product
Assistants, copilots and AI features that fit your product and the workflows your users already have.
Features, assistants and agents
- 02
Ground it in your data
Retrieval over your own documents and systems, with sources cited, so answers stay current and easy to check.
Retrieval, embeddings and context
- 03
Evaluate and release
Evals on every prompt and model change, guardrails, and a release process that ships only what clears the bar.
Evals, guardrails and release
- 04
Operate and improve
Quality, cost and latency watched in production, with routing and prompts tuned as usage grows.
Monitoring, cost and evolution
Need a related team around your AI developers?
Find the right roleHow teams use us
The roles we brought in, and what each team achieved. Examples of use, not guarantees.
- US product company01
Dedicated product pod
AI assistant team
We provided generative AI engineers to take an in-product assistant from demo to launch, with evals in place before the first release.
Capability mix
- AI Solutions Architect
- LLM Engineer
- Delivery Lead
LangChain · LangGraph · Qdrant · Python
- Faster
- path to launch
- Measured
- answer quality
- US enterprise platform02
Architecture and delivery
Enterprise knowledge search
We added specialists to bring cited answers over the platform’s own documents into its product, inside existing access controls.
Capability mix
- AI Solutions Architect
- LLM Engineer
- Platform Engineer
LangChain · pgvector · FastAPI · Python
- Grounded
- answers with sources
- Secure
- data boundaries
- US financial services03
Augmented squad
Compliant AI features
We placed generative AI engineers inside the client’s strict security and compliance workflow to ship AI features on self-hosted models.
Capability mix
- LLM Engineer
- AI Evaluation Engineer
- Security Engineer
LangGraph · Hugging Face · vLLM · Python
- Compliant
- AI releases
- Lower
- model costs
Client details are kept private. Roles show the skills each engagement used. Results are examples, not guarantees. Related reading: Case studies, Hiring insights on the blog, How we build teams and Prototype to launch.
One team. Two locations.
Your leaders own the product and the architecture. Our India-based engineers join your way of working, backed by delivery across the USA, India, Canada and Mexico.
- Start small with the AI developer you need now.
- Work your way in your codebase, tools and quality process.
- Grow when needed by pairing AI developers with a dedicated delivery pod.
- 01AI Solutions ArchitectArchitecture
- 02LLM EngineerCore delivery
- 03AI Evaluation EngineerQuality
- 04LLMOps EngineerPlatform
- Rituals
- Daily overlap
- Ownership
- Sprint outcomes
- Start
- Roadmap-led
Is this a good fit?
- 01You need AI developers to ship RAG, agents and evals in your product stack.
- 02You want to embed AI developers in your team or pair engineers with a dedicated delivery pod.
- 03You need engineers who follow your security and release process.
- 04You want India-based engineers who work closely with your US team.
How it works
Leadership context
Discovery call
Tell us about your product, the AI gap and whether you need an architect, LLM engineer, evaluation engineer or LLMOps engineer.
What we cover
- Your goals
- The team gap
- Your AI context
Team shape
Pick the model
Choose one AI developer, a small AI squad, or developers paired with a delivery pod, and agree how the team works with yours.
What we cover
- Engagement model
- Seniority mix
- Working hours
Shortlist
Meet vetted options
Within days, review generative AI engineers matched to your stack, your domain and the way you deliver.
What we cover
- Matched profiles
- Evidence of skills
- Availability
Your decision
Interview and select
Interview the shortlist yourself, test the technical fit and choose who joins.
What we cover
- Technical interview
- Team fit
- Your final pick
First sprint
Onboard and kick off
Access, introductions and a walkthrough of the codebase, then the first tickets inside your sprint.
What we cover
- Access and tools
- Codebase walkthrough
- First commit
 Step 01
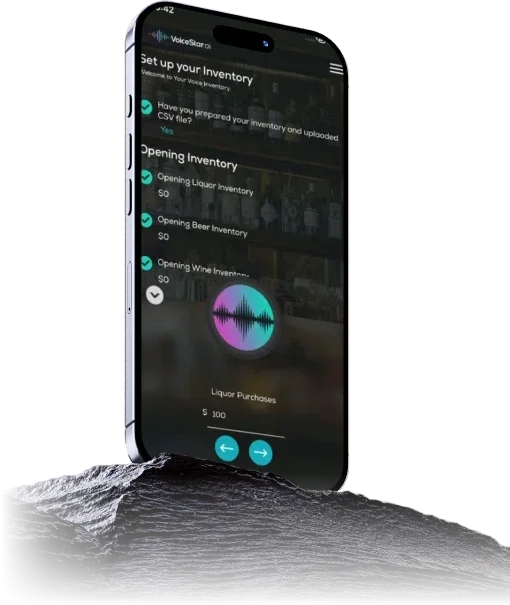
AI developer case studies / 02
Public products that used speech, voice or AI features hired AI developers would own. Open a study for the brief, platform and stack.
AI developer client stories / 01
Clients who needed specialist product work adjacent to hired AI developers, in their own words.
They treated our XR roadmap like their own. Every sprint ended with something we could put in front of users.
01How do I hire AI developers for my team?
Hire AI developers to ship RAG, agents and evals that hold up in production. Embed one engineer in your team or add a generative AI squad. You interview the shortlist and choose who joins.
02What generative AI skills can we hire for?
AI architecture, retrieval-augmented generation, agents and tool use, LangChain and LangGraph, vector search, evals and guardrails, model routing, fine-tuning and self-hosted models.
03Do hired AI developers fine-tune, or use retrieval?
Retrieval first: it keeps answers current and citable. We fine-tune when evals show a smaller tuned model beats it on cost or quality.
04Which models do you work with?
Anthropic, Google, OpenAI, Mistral and open-weight models you host yourself. The router keeps you free to switch.
05How do you stop the model making things up?
Answers must cite retrieved sources, groundedness is scored on every run, and a release can’t ship below its threshold.
06Where does our data go?
Where you decide. We can keep embeddings in your own database and run open models inside your cloud account.
07Can we embed AI developers in our team or hire a pod?
Both. Add one AI developer through staff augmentation, or pair AI engineers with a dedicated delivery pod when you need features and release in the same team.
08What affects the cost of hiring AI developers?
Seniority, US workday overlap, and whether you hire one developer or a pod. The planner on this page uses a $90/hr onshore and $32/hr offshore planning rate, 160 hours a month. It is an estimate, not a JumpGrowth quote.
09Is this staff augmentation or a managed delivery team?
Both. Add one AI developer, a small team, or a full pod with its own lead.
10Can we start with one AI developer?
Yes. Most teams start with one AI developer in a clear gap and add people once the fit is proven.
11Can we interview AI developers before we choose?
Always. You see the profiles, run your own interviews and make the final call.
12Can we scale the team after the first AI developer starts?
Yes. Add people as the roadmap grows, or move from one AI developer to a managed pod with its own lead.
Hire AI developers
Tell us whether you need an AI architect, LLM engineer, evaluation engineer or LLMOps engineer, and whether they join your team or a pod.